Key takeaways
- Use a checklist retrieval log as the unit of evidence.
- Measure retrieval time, failed searches, stale-document use, escalation rate.
- Keep alternative explanations and exclusions visible.
- Named people retain consequential and irreversible decisions.
Table of contents
Research question and scope
How can teams measure checklist retrieval friction during onboarding? This section examines research question and scope through a narrowly defined checklist retrieval log. The proposed design is an OnboardingEmployees analysis, not a claim made by the cited authors.
The record keeps the task, instruction version, access level, reviewer, timestamps, questions, corrections, and final disposition together. Counts and exclusions remain visible so a clean average cannot conceal a consequential exception.
Interpretation stays conditional. Differences can reflect case difficulty, prior experience, reviewer availability, changing instructions, missing access, or incomplete records. The design therefore supports a bounded local decision, not a universal benchmark.
| Evidence element | Recorded field | Interpretation limit | Decision use |
|---|---|---|---|
| Assignment | Task and instruction version | Context, not proof | Define sample |
| Trace | checklist retrieval log | Depends on complete capture | Reconstruct events |
| Measures | retrieval time, failed searches, stale-document use, escalation rate | No universal threshold | Compare stable samples |
| Boundary | Named reserved authority | Scope stays explicit | Hold, narrow, or test |
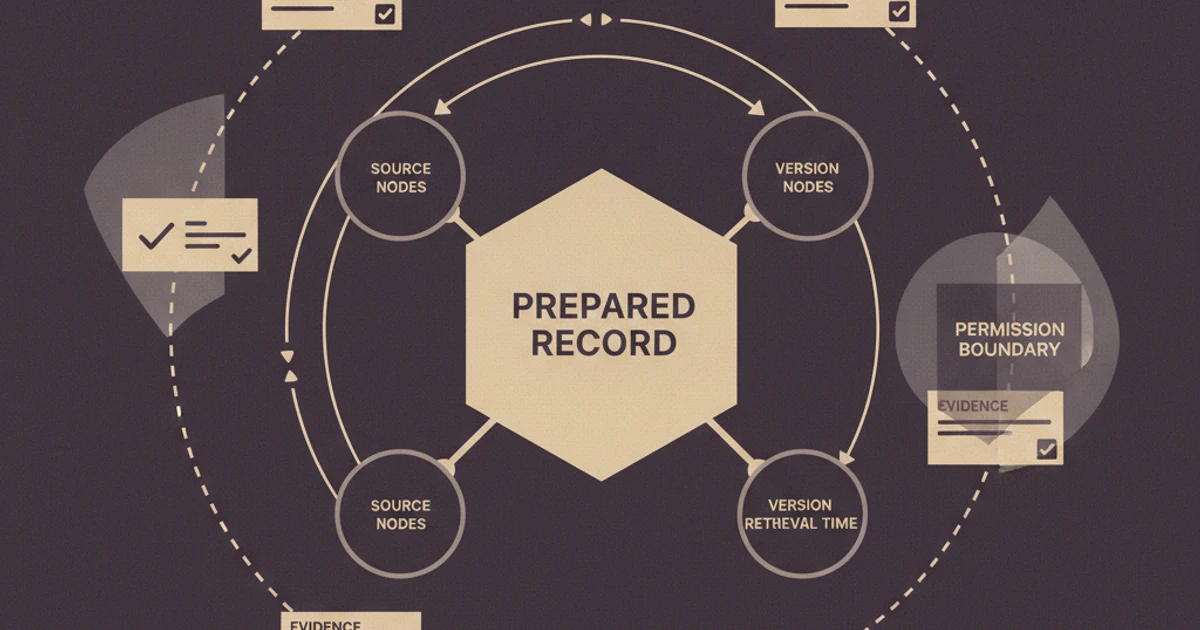
Evidence record design
How can teams measure checklist retrieval friction during onboarding? This section examines evidence record design through a narrowly defined checklist retrieval log. The proposed design is an OnboardingEmployees analysis, not a claim made by the cited authors.
The record keeps the task, instruction version, access level, reviewer, timestamps, questions, corrections, and final disposition together. Counts and exclusions remain visible so a clean average cannot conceal a consequential exception.
Interpretation stays conditional. Differences can reflect case difficulty, prior experience, reviewer availability, changing instructions, missing access, or incomplete records. The design therefore supports a bounded local decision, not a universal benchmark.
Measurement definitions
How can teams measure checklist retrieval friction during onboarding? This section examines measurement definitions through a narrowly defined checklist retrieval log. The proposed design is an OnboardingEmployees analysis, not a claim made by the cited authors.
The record keeps the task, instruction version, access level, reviewer, timestamps, questions, corrections, and final disposition together. Counts and exclusions remain visible so a clean average cannot conceal a consequential exception.
Interpretation stays conditional. Differences can reflect case difficulty, prior experience, reviewer availability, changing instructions, missing access, or incomplete records. The design therefore supports a bounded local decision, not a universal benchmark.
Alternative explanations
How can teams measure checklist retrieval friction during onboarding? This section examines alternative explanations through a narrowly defined checklist retrieval log. The proposed design is an OnboardingEmployees analysis, not a claim made by the cited authors.
The record keeps the task, instruction version, access level, reviewer, timestamps, questions, corrections, and final disposition together. Counts and exclusions remain visible so a clean average cannot conceal a consequential exception.
Interpretation stays conditional. Differences can reflect case difficulty, prior experience, reviewer availability, changing instructions, missing access, or incomplete records. The design therefore supports a bounded local decision, not a universal benchmark.
Authority and privacy boundaries
How can teams measure checklist retrieval friction during onboarding? This section examines authority and privacy boundaries through a narrowly defined checklist retrieval log. The proposed design is an OnboardingEmployees analysis, not a claim made by the cited authors.
The record keeps the task, instruction version, access level, reviewer, timestamps, questions, corrections, and final disposition together. Counts and exclusions remain visible so a clean average cannot conceal a consequential exception.
Interpretation stays conditional. Differences can reflect case difficulty, prior experience, reviewer availability, changing instructions, missing access, or incomplete records. The design therefore supports a bounded local decision, not a universal benchmark.
Method and source mapping
How can teams measure checklist retrieval friction during onboarding? This section examines method and source mapping through a narrowly defined checklist retrieval log. The proposed design is an OnboardingEmployees analysis, not a claim made by the cited authors.
The record keeps the task, instruction version, access level, reviewer, timestamps, questions, corrections, and final disposition together. Counts and exclusions remain visible so a clean average cannot conceal a consequential exception.
Interpretation stays conditional. Differences can reflect case difficulty, prior experience, reviewer availability, changing instructions, missing access, or incomplete records. The design therefore supports a bounded local decision, not a universal benchmark.
Limitations and conclusion
How can teams measure checklist retrieval friction during onboarding? This section examines limitations and conclusion through a narrowly defined checklist retrieval log. The proposed design is an OnboardingEmployees analysis, not a claim made by the cited authors.
The record keeps the task, instruction version, access level, reviewer, timestamps, questions, corrections, and final disposition together. Counts and exclusions remain visible so a clean average cannot conceal a consequential exception.
Interpretation stays conditional. Differences can reflect case difficulty, prior experience, reviewer availability, changing instructions, missing access, or incomplete records. The design therefore supports a bounded local decision, not a universal benchmark.
Sources and methodology
Documentary synthesis of three public sources mapped to a fictional onboarding workflow. Source guidance is separated from OnboardingEmployees analysis. No employee records, interviews, experiment, or company outcome data were used.
- NIST SP 800-53 Rev. 52020. Control guidance for access, accountability, and documented review.
- AHRQ TeamSTEPPS 3.02023. Evidence-based teamwork tools for handoffs, check-backs, and shared awareness.
- Institute of Education Sciences, Organizing Instruction and Study to Improve Student Learning2007. Practice guide covering worked examples, retrieval, spacing, and transfer.
Source count: 3. Last verification date: September 7, 2026.
Related research
FAQ
What is the unit of analysis?
The proposed unit is a checklist retrieval log.
What should a team measure?
The proposed measures are retrieval time, failed searches, stale-document use, escalation rate.
Does this prove causation?
No. This documentary design describes a local observation method and cannot establish a causal effect.
What are the main limitations?
Incomplete records, changing cases, reviewer differences, and local context limit interpretation.
Who retains consequential decisions?
Named authorized people retain employment, legal, security, financial, credential, contact, and irreversible decisions.
Review the full research library, compare cluster coverage inside recruiting operations, and pair these findings with our VA candidate screening support.